Learn
What we learned making AI video
Building ShowMaker, we test every video model on real episodes. Here is what worked, what broke and why, with the real clips and the prompts we sent.
 Video models
Why we don't use start and end frames
When you give Seedance 2.5 or Wan 3.0 a start frame and an end frame, they stop using your character sheets and voice samples. The clip lands on your pictures, but your characters can stop looking and sounding like themselves. So ShowMaker never uses frames: every clip gets the character sheets and voices as references, and the clip before it for the join.29 October 2026 4 min read Prompt guides
Seedance 2.5 prompt guide: what worked for us
Keep it short. One style line, one sentence on what is happening, the beats with their seconds and the spoken lines inside them, then one line per picture and voice saying what it is. Our 1,000-character prompts beat our 5,000-character ones in blind tests.29 October 2026 4 min read Prompt guides
Wan 3.0 prompt guide: what worked for us
A good Seedance prompt already works on Wan 3.0. Our first Wan clips used our Seedance prompts unchanged, pictures, voices and previous clip included, and Wan accepted every one of them. Wan's own guide asks for three small changes: name files as "Image 1" and "Audio 1", write "One continuous shot" when a clip has no cut, and write "No dialogue" when nobody talks.29 October 2026 6 min read Video models
Seedance 2.5 vs Wan 3.0 vs MiniMax H3: one clip, three models
Given the same pictures and the same prompt, all three made a usable 15-second clip of the same scene, at 480p. They differ less in quality than in what they take: how long a clip can be, how many pictures and voice samples you can send, what sharpness you can ask for, and the price per second. Pick by what your episode needs, then judge the clips with your own eyes.29 October 2026 5 min read Look and light
Why AI video looks flat, and the fix that worked
The model copies the room from your scene picture. Ours drew every place as an empty set, and our prompt told the model to ignore the lighting in every picture, so clips came back clean, evenly lit and lifeless. A lived-in scene picture, and a shorter prompt that says the look first, fixed it.29 October 2026 4 min read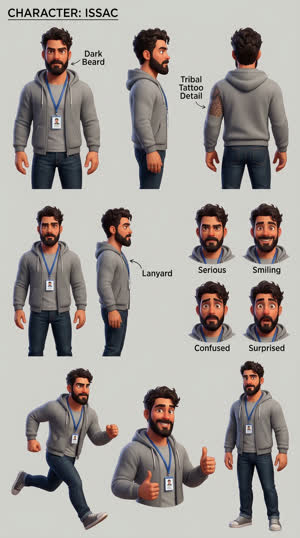 Characters
Consistent characters in AI video: same face, same voice, no jumps
A video model has no memory between clips. Draw each character once for the episode and send that drawing with every clip, send each speaker's voice sample with a line that says whose it is, and join clips by sending the end of the clip before. Then end every clip on a finished movement, not a freeze.29 October 2026 3 min read